arXiv 2026
DoSA: Dots Sparse Attention
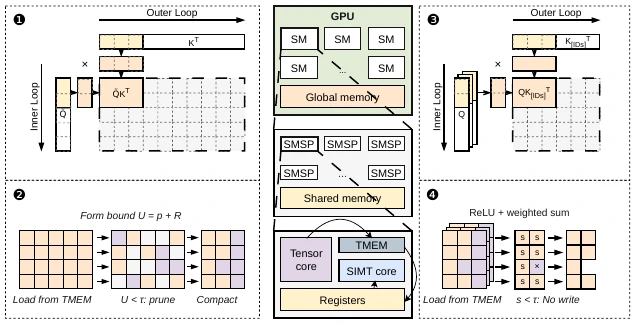
A lossless sparse-attention indexer that uses certified bounds to skip unnecessary scoring while preserving exact Top-K token selection.
REDstar@Dots Studio · Xiaohongshu Inc.
I work on efficient architectures for long-context large language models and parameter-efficient fine-tuning.
I am currently with Dots Studio at Xiaohongshu Inc. My research focuses on improving the efficiency and scalability of long-context LLMs through architectural innovations, as well as developing effective parameter-efficient fine-tuning methods. I have served as a reviewer for NeurIPS, ICML, ICLR, CVPR, TPAMI, etc.
I received my Ph.D. from the Institute for Artificial Intelligence at Peking University, advised by Prof. Muhan Zhang, and my master’s degree from Harbin Institute of Technology, Shenzhen, advised by Prof. Guangming Lu.
During my master’s and Ph.D. studies, I spent a total of four years at Tencent YouTu as both an intern and a full-time researcher, collaborating with Xing Sun, Hao Cheng, and Ke Li.
Research
arXiv 2026
A lossless sparse-attention indexer that uses certified bounds to skip unnecessary scoring while preserving exact Top-K token selection.
ASPLOS 2026 · Summer cycle
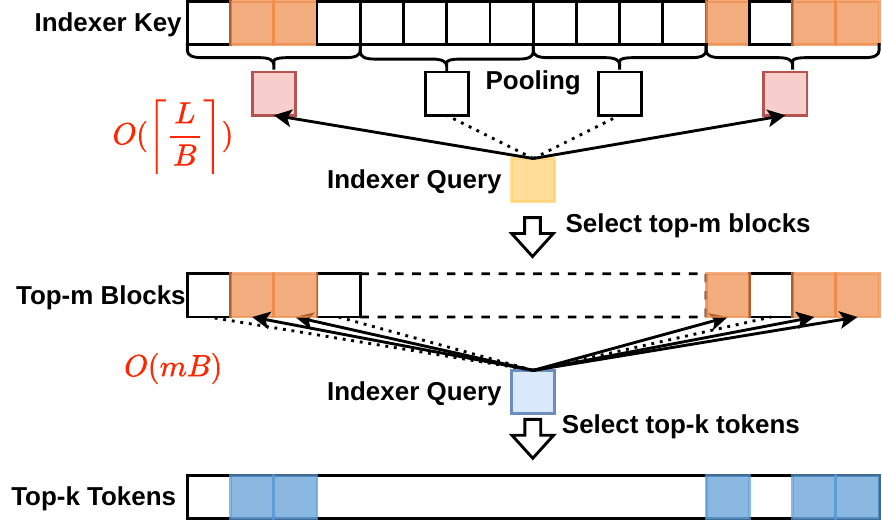
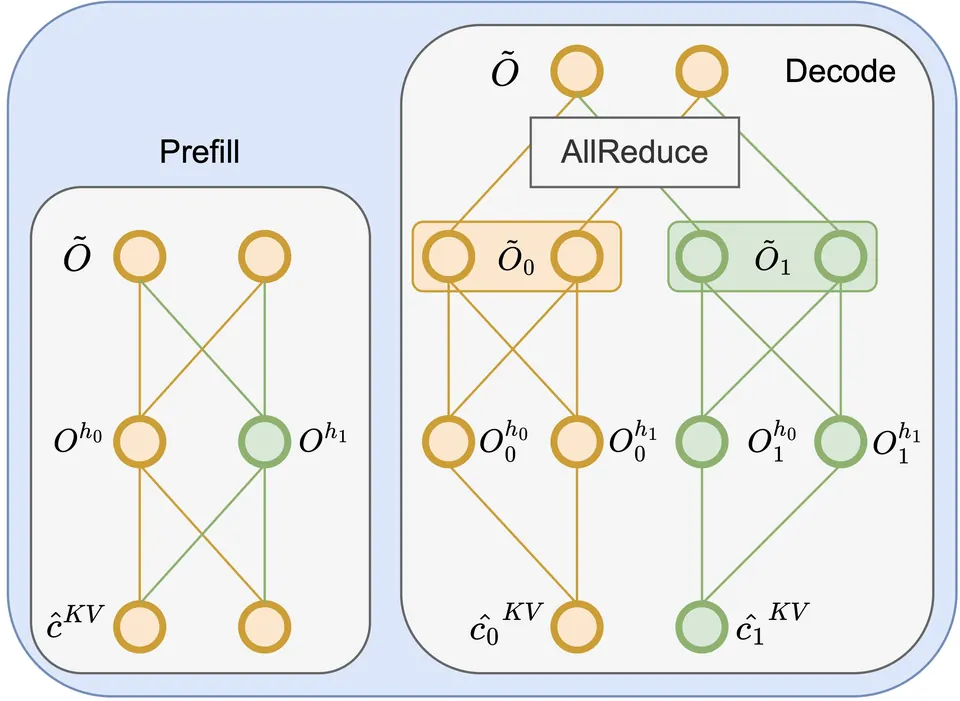
An attention mechanism designed for tensor parallelism and prefill–decode disaggregation.
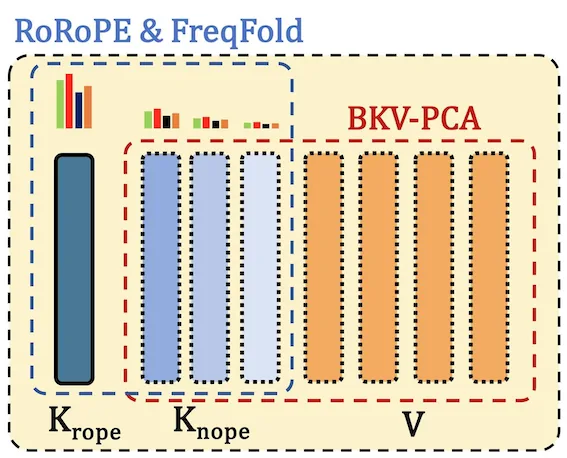
NeurIPS 2025 · Spotlight · Top 3.19%
A theoretical and practical study of MLA, including conversions of Llama and Qwen models to the DeepSeek-style architecture.
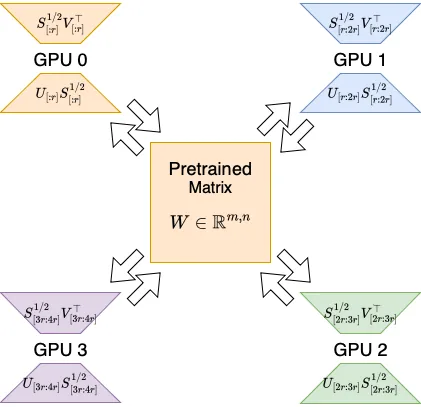
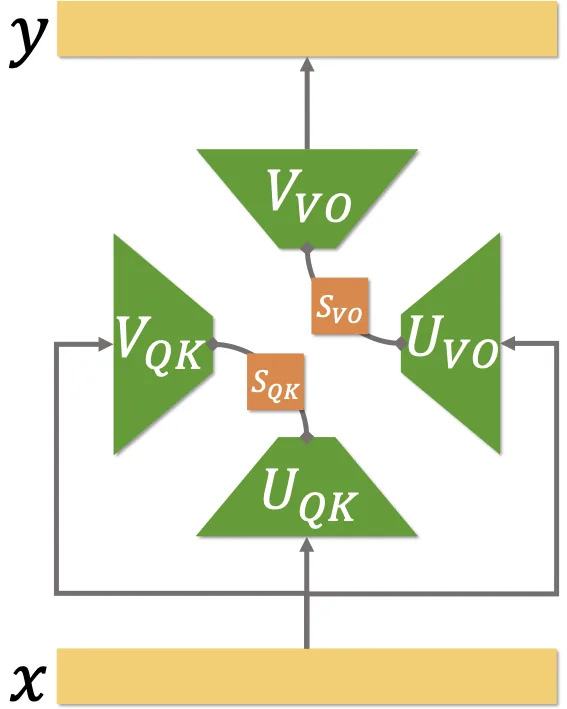
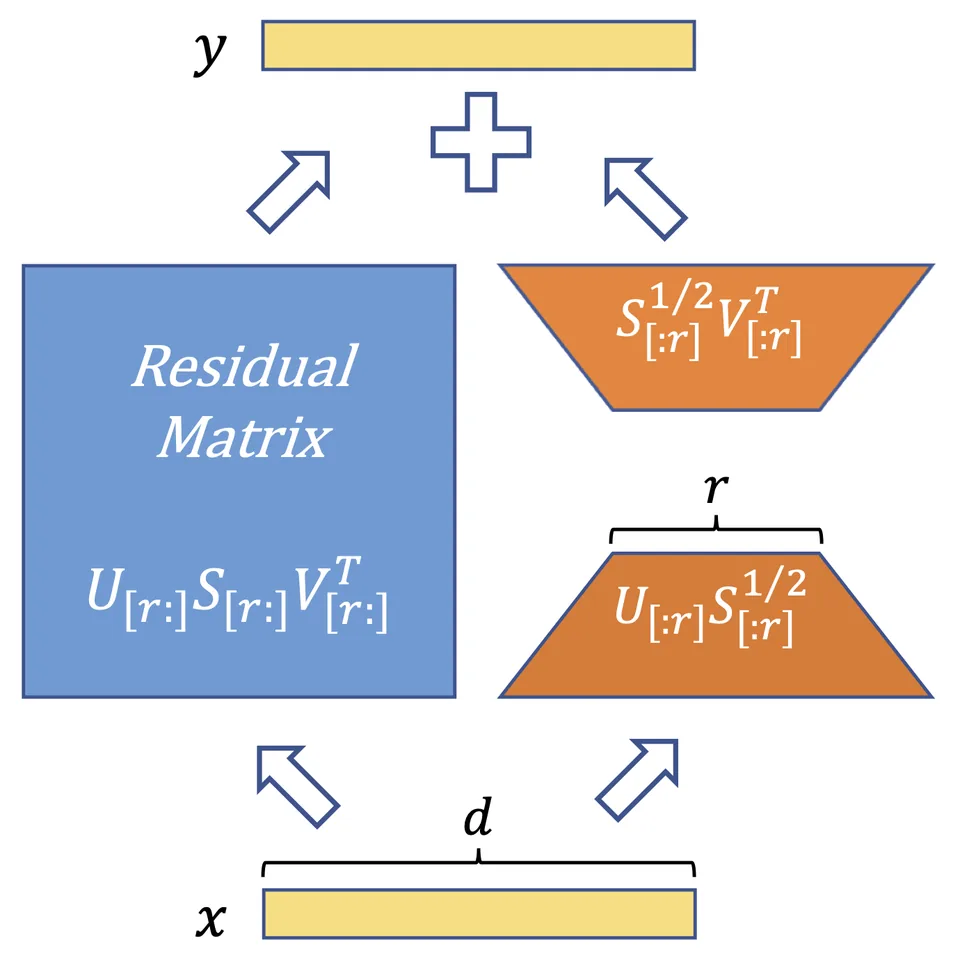
NeurIPS 2024 · Spotlight · Top 2.08%
A faster and more effective initialization method for low-rank adaptation.
* Equal contribution.
Contact
I welcome conversations about foundation model architectures, model adaptation, and efficient inference.